 GoodMem
Build and tune hybrid search
Run MiniLM and SPLADE with the latest GoodMem release, compare retrieval results, and tune hybrid search weights on SQuAD.
Combine semantic and term-based retrieval in a single GoodMem space. This guide uses the latest GoodMem release with MiniLM for semantic similarity and SPLADE for learned sparse retrieval. SPLADE represents text through weighted vocabulary terms and expands queries with related terms.
You'll run both models locally, search a small collection, and adjust how much each model contributes to the ranking. The accompanying SQuAD benchmark reaches 0.8147 MRR@10 and 92.9% Hit@10 with a dense-to-sparse ratio of about 1:0.17. Start with the small example below, or jump to the measured results and SQuAD benchmark.
Start the local example
You need Python 3.12, Docker Engine, and Docker Compose on x86-64 Linux. This example uses CPU inference; a GPU and external model API keys are not required. The first startup downloads the server images and both models.
git clone https://github.com/PAIR-Systems-Inc/goodmem-docs-examples.git
cd goodmem-docs-examples/hybrid-search
python3 -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt

python -c 'import secrets; from pathlib import Path; Path(".env").open("x").write("GOODMEM_DB_PASSWORD=" + secrets.token_urlsafe(24) + "\n")'
chmod 600 .env
docker compose up -d
The Compose file
pulls the latest GoodMem server image and pins the tested TEI and PostgreSQL
images. It starts PostgreSQL, GoodMem, sentence-transformers/all-MiniLM-L6-v2, and
naver/splade-cocondenser-ensembledistil. SPLADE starts with --pooling splade.
Wait for model loading to finish:
until curl -fsS http://127.0.0.1:18081/health >/dev/null; do sleep 5; done
until curl -fsS http://127.0.0.1:18082/health >/dev/null; do sleep 5; done
python setup.py
source run/credentials.env
setup.py initializes the new server, registers both embedders, and creates a
space with both models. It saves the resource IDs in run/resources.json and
the API key in the Git-ignored, mode-0600 run/credentials.env. The REST endpoint
is http://127.0.0.1:18080; the CLI's gRPC endpoint is
http://127.0.0.1:19090. The console is at http://127.0.0.1:18080/console.
The models use http://dense:80 and http://sparse:80 inside the shared Docker
network. An embedder endpoint must be reachable from the GoodMem server.
localhost inside the server container refers to that container, not the host
or another model container.
If these host ports are occupied, configure the port variables described in the
example README.
For an existing server, export its GOODMEM_BASE_URL and GOODMEM_API_KEY and
pass existing model IDs with setup.py --dense-id ... --sparse-id ....
Compare three retrieval configurations
python demo.py --ratio 0.168702397557The script inserts six short energy-related documents, waits for processing to finish, and runs the same query with dense-only, sparse-only, and hybrid weights. It prints the three highest-ranked results and their scores for each configuration.
The query asks which device changes photovoltaic output to AC. Look for the
sentence about a photovoltaic inverter in the output: it appears first with
dense-only scoring and second with sparse-only and hybrid scoring. Each section
shows the model weights, ranked sentences, and scores, so you can see how changing
weights changes the ordering. Try another question with --query or change the
sparse coefficient with --ratio.
Each input is stored without further chunking, so this example has one chunk per memory. In document collections with multiple chunks per memory, retrieval and the requested result count operate on chunks.
Set weights for an individual query
The Python SDK accepts per-embedder overrides in space_keys:
import json
import os
from goodmem import Goodmem

resources = json.load(open("run/resources.json"))
with Goodmem(
    base_url=os.environ["GOODMEM_BASE_URL"],
    api_key=os.environ["GOODMEM_API_KEY"],
    timeout=120,
) as client:
    events = client.memories.retrieve(
        message="Which device changes the electrical output of photovoltaic cells to AC?",
        space_keys=[{
            "space_id": resources["space_id"],
            "embedder_weights": [
                {"embedder_id": resources["dense"], "weight": 1.0},
                {"embedder_id": resources["sparse"], "weight": 0.168702397557},
            ],
        }],
        requested_size=3,
        fetch_memory=True,
        stream=False,
    )
    for event in events:
        if event.status:
            raise RuntimeError(f"{event.status.code}: {event.status.message}")
        if event.retrieved_item and event.retrieved_item.chunk:
            print(event.retrieved_item.chunk.chunk.chunk_text)
Weights do not need to sum to 1. With dense weight 1 and sparse weight r,
the merged score is the dense score plus r times the sparse score. This
setup reports negative inner products, so lower (more negative) scores rank
first. Each model has its own score scale; the weights control how those scales
combine. A zero weight removes that model's contribution to the score. Both
embedders contribute candidates in all three configurations.
These overrides apply to the current query and do not change the space defaults.
Choose a ratio using evaluation
Start with a dense-to-sparse ratio of about 1:0.17 for this model pair. The commands above use the exact coefficient selected on 1,000 SQuAD tuning questions. The results below compare all five scoring configurations. To reproduce the benchmark or tune weights for your collection, continue with the evaluation workflow.
Measured results
MRR@10 measures how highly the first accepted answer ranks in the top ten results.
Hit@k is the percentage of questions with an accepted answer in the first k
results. Higher values are better for both metrics.
All numbers below are from the test questions, evaluated after selecting the ratio on the separate tuning split.
| Scoring configuration | MRR@10 | Hit@1 | Hit@5 | Hit@10 |
|---|---|---|---|---|
| Dense-only scoring (1:0) | 0.7069 | 60.7% | 83.9% | 90.2% |
| Sparse-only scoring (0:1) | 0.8117 | 74.0% | 90.3% | 92.6% |
| Hybrid (1:0.005) | 0.7553 | 66.8% | 87.2% | 91.9% |
| Equal weights (1:1) | 0.8122 | 74.0% | 90.3% | 92.7% |
| Selected ratio (about 1:0.17) | 0.8147 | 74.2% | 90.7% | 92.9% |
All five configurations returned results for every test query (100% coverage). The searchable corpus contained 10,250 sentences from 48 SQuAD articles. The experiment used 1,000 tuning questions from 24 articles and 1,000 test questions from the other 24. One question had no complete answer span in a sentence and was excluded before sampling.
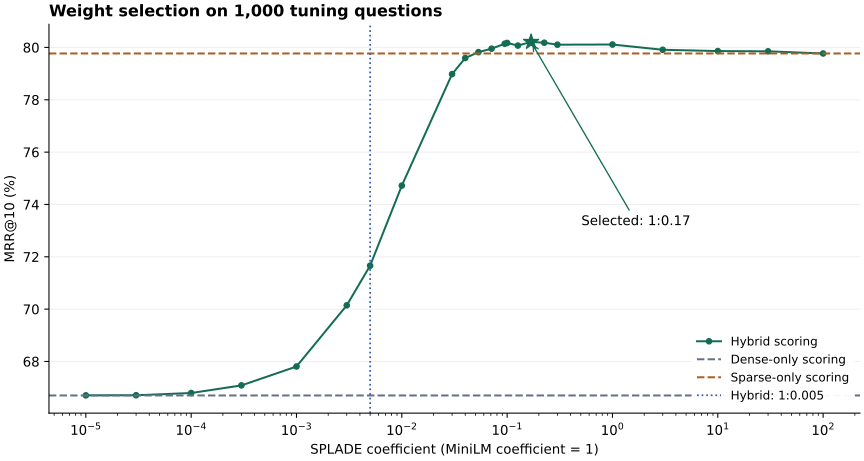
The tuning curve levels off around its peak, with nearby ratios producing similar scores.
Compared with 1:0.005, the selected ratio improved test MRR@10 by 0.0593 (95% paired article-cluster bootstrap interval 0.0434 to 0.0714). Compared with dense-only scoring, the difference was 0.1078 (0.0911 to 0.1209).
The selected hybrid configuration has the highest measured MRR. Its difference from sparse-only scoring is 0.0030, with a 95% interval of −0.0019 to 0.0091. Because that interval includes zero, the comparison is inconclusive on this test set. Use the same evaluation workflow to compare configurations on your application's queries.
The measurements used MiniLM and SPLADE with pinned model revisions, TEI
on CPU, one sentence per memory, no postprocessor, requested_size=10, and the
server's default HNSW settings. Use the latest GoodMem release to run the example.
The run summary records all tuning points, held-out metrics, confidence intervals, model revisions, dataset hashes, and the server version. The paired question ranks provide the per-question data behind the reported comparisons.
Evaluate on SQuAD
This benchmark stores 10,250 sentences in a separate space, selects weights on 1,000 tuning questions, and evaluates them on 1,000 questions from different articles. It reuses the models from the small example and runs thousands of queries, so allow more time than the six-document demo.
Prepare an isolated benchmark
Continue in the hybrid-search directory with the virtual environment active
and GoodMem credentials loaded:
DENSE_ID=$(python -c 'import json; print(json.load(open("run/resources.json"))["dense"])')
SPARSE_ID=$(python -c 'import json; print(json.load(open("run/resources.json"))["sparse"])')
python setup.py --output-dir run/benchmark --name 'SQuAD hybrid benchmark' \
  --dense-id "$DENSE_ID" --sparse-id "$SPARSE_ID"
SPACE_ID=$(python -c 'import json; print(json.load(open("run/benchmark/resources.json"))["space_id"])')

mkdir -p squad_data
curl -fL https://raw.githubusercontent.com/rajpurkar/SQuAD-explorer/master/dataset/dev-v1.1.json \
  -o squad_data/dev-v1.1.json
python insert_squad_sentences_goodmem.py --space-id "$SPACE_ID" --dry-run
python insert_squad_sentences_goodmem.py --space-id "$SPACE_ID" \
  --output run/benchmark/manifest.json --sample-size 1000 --seed 42
The loader:
- Splits SQuAD paragraphs into sentences using the bundled sentence breaker.
- Maps each annotated answer span to a sentence that contains the complete answer. A question can have several accepted answer sentences. Questions with no complete answer sentence are counted and excluded before sampling.
- Stores each sentence as one memory with further chunking disabled.
- Shuffles article titles deterministically, assigns half to tuning and half to testing, and samples 1,000 questions from each group.
- Waits for every memory in the corpus to finish processing before evaluation.
The manifest records the dataset hash, corpus, question IDs, split, seed, registered models, and server version. Rerunning the loader resumes by stable memory IDs; it rejects unexpected memories or a conflicting manifest.
The searchable corpus includes the answer sentences for both groups. Tuning questions select the weights; questions from the separate test articles measure the selected configuration.
Search the ratio space
python optimize_embedder_weights.py --manifest run/benchmark/manifest.json \
  --output-dir run/benchmark/search --threads 4
The search fixes the dense coefficient at 1 and varies the sparse coefficient. The initial grid includes dense-only, sparse-only, 1:0.005, 1:1, and logarithmically spaced sparse coefficients from 0.00001 through 100. One nine-point logarithmic refinement explores the neighborhood of the best tuning result. The optimizer selects the tested ratio with the highest tuning MRR.
selection.json freezes the winning ratio before test queries are issued. The
test phase compares that choice with dense-only, sparse-only, 1:0.005, and 1:1.
If scores tie during tuning, it prefers a single-model score over a hybrid score.
All configurations use the same two-embedder space and candidate discovery. “Dense-only” and “sparse-only” refer to scoring weights of 1:0 and 0:1. The benchmark compares ranking quality; measuring deployment cost or latency calls for a separate benchmark with the intended model configuration.
To change the search grid for a new experiment:
python optimize_embedder_weights.py --manifest run/benchmark/manifest.json \
  --output-dir run/another-search --ratios '0,0.001,0.003,0.005,0.01,0.03,0.1,1,sparse' \
  --fine-points 9
Use a fresh test set when refining the models or search grid after reviewing test results, so the next evaluation measures performance on unseen questions.
Interpret the output
- MRR@10: average reciprocal rank of the first accepted answer sentence, with zero for questions whose answer is absent from the first ten results.
- Hit@k: fraction of questions with at least one accepted answer sentence in
the first
kresults. Because some questions have multiple accepted sentences, any accepted answer counts as a hit. - Coverage: fraction of queries returning any results.
The evaluator checks that ingestion and retrieval complete successfully before reporting metrics. If a run stops with an error, resolve it and rerun the command to resume completed evaluations.
The held-out comparison joins results by question ID. It reports a paired article-cluster bootstrap interval for the MRR difference: whole articles are resampled so questions from the same article remain together. The seed and number of resamples are recorded. The intervals describe sampling uncertainty for this dataset.
Inspect misses
Each successful evaluation writes its weights, metrics, question IDs, ranks,
and retrieved memory IDs to a JSON file under search/evaluations/. Choose an
evaluation file from that directory to inspect:
python analyze_missing_gt_similarity.py --manifest run/benchmark/manifest.json \
  --evaluation PATH_TO_EVALUATION_JSON --limit 10 --search-size 100 \
  --output run/benchmark/misses.json
For each miss, the analyzer compares the selected weights with dense-only and sparse-only scoring. It shows returned text, scores, accepted memory IDs, and the first accepted answer's rank if found. It uses the same GoodMem API and embedders as the experiment. The larger search size helps locate accepted answers beyond the original top ten; it can also change the candidate pool and ranking.
Reproduce and adapt the experiment
The example source
includes pinned dependencies, the Compose environment, all scripts, and regression
tests. Keep the manifest, selection.json, summary.json, and evaluation files
with your results. Completed evaluations can resume from matching caches; changed
questions, weights, retrieval depth, or manifests use different cache keys.
Create a new run when changing the corpus, model weights, chunking, or server configuration. Replace SQuAD with representative questions and accepted answers from your application before adopting the measured ratio as a default.
Troubleshoot and stop
- Check model loading with
docker compose logs dense sparse. - For ingestion errors, inspect the affected memory's processing history.
- For retrieval errors, use the status message to identify and resolve the cause.
docker compose stopThis stops the example while preserving its database and model cache.